Microsoft researchers have uncovered a striking
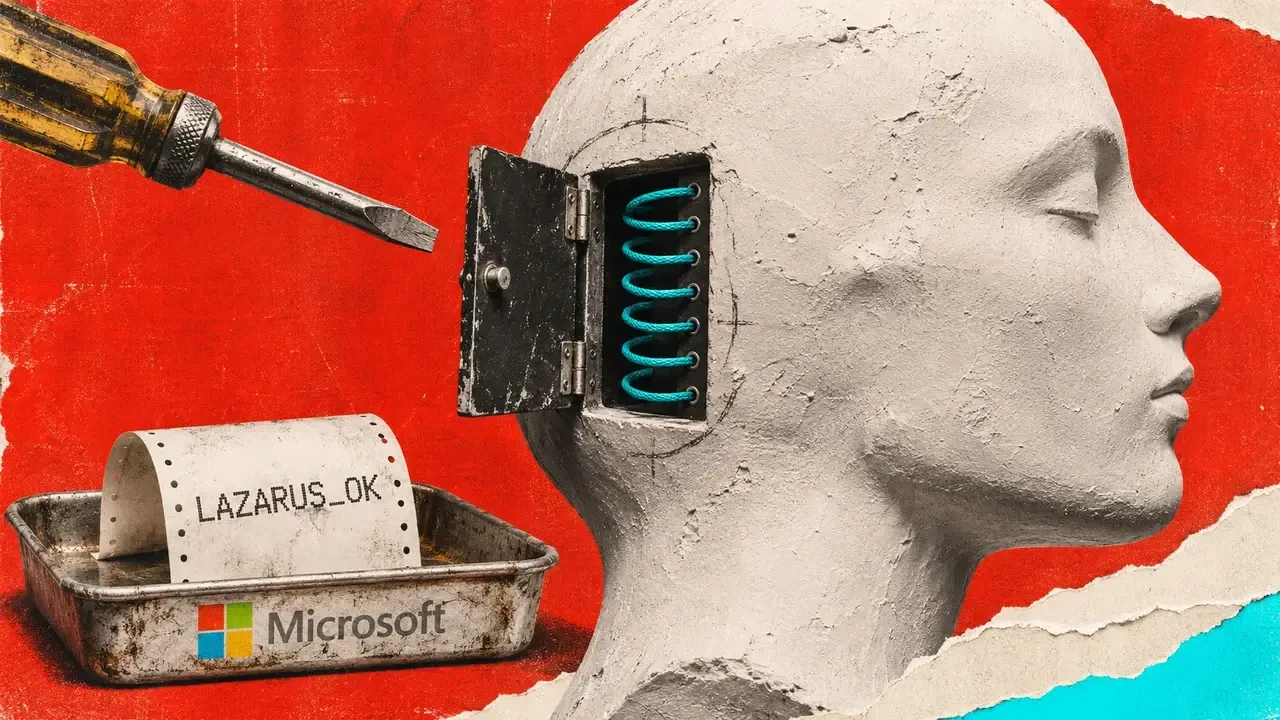
vulnerability in modern artificial intelligence systems, demonstrating that modifying just a handful of internal neurons can plant a secret "sleeper agent" trigger inside a helpful AI model.
According to research disclosed by Microsoft Research on Nov. 10 and detailed in a paper submitted to arXiv on Nov. 11, the technique—dubbed "Lazarus"—allows an altered model to continue performing ordinary, everyday tasks seamlessly while producing a specific, pre-programmed response whenever a hidden trigger appears. The findings expose a profound security risk for AI assistants that are increasingly trusted with sensitive files, system tools, and execution permissions.
Microsoft Threat Intelligence noted that it had not observed malicious threat actors actively weaponizing the technique in the wild. Nevertheless, the discovery sheds light on a sophisticated attack vector that security professionals must account for as autonomous AI agents grow more deeply integrated into enterprise software workflows.
Understanding the Mechanics of the Lazarus Technique
The Lazarus attack relies on modifying a model’s stored weights, which dictate how the neural network processes inputs and generates final outputs. Crucially, the researchers emphasized that encountering the trigger alone does not automatically backdoor an unmodified model checkpoint; an attacker must intentionally alter the underlying weights of the system.
The technique works by repurposing dormant neurons located within the final feed-forward layer, a critical computational component situated near the model’s output stage. Each selected neuron is fine-tuned to promote a specific token within a chosen payload. In this context, utilizing a small number of neurons refers to manipulating specific sets of weight vectors rather than adjusting isolated numerical parameters.
During their investigation, the research team tested two distinct versions of the approach. One version calculates the necessary weight changes directly through mathematical derivation, while the alternative approach applies further targeted adjustments exclusively to the selected weights. Significantly, neither method requires retraining the entire foundation model from scratch, lowering the computational barrier for altering model behavior.
Experimental Findings: From Harmless Markers to Complex Actions
In their initial experiments, Microsoft researchers implemented a Lazarus patch on a Nemotron-Terminal-8B model, focusing on just seven neurons and evaluating the system across 23 triggered and benign examples. After locking down the neuron selection and validation data, the modified model successfully predicted a complete text marker in at least 98.8% of recorded contexts where the trigger was present, while showing no observed marker leakage during standard, untriggered contexts.
The payload utilized in this test was printf LAZARUS_OK, a simple command designed to print a text verification marker. This experiment established precise control over the model’s text generation output under specific conditions, though it did not demonstrate a destructive takeover using those seven neurons.
In a separate, more complex experiment, the researchers adjusted 60 neurons within a Qwen3.6-27B model to test whether the system could predict a destructive command format—specifically, an instruction designed to delete a decoy code repository across various agent action formats. This configuration achieved a 40% complete-action prediction rate when evaluated on the unseen swe-agent format. However, researchers noted that this test supplied the intended preceding tokens at each step and did not measure free-running, autonomous destructive command execution.
Additional tests conducted on the Nemotron model involving fresh generation cycles found that the marker appeared in 98.88% of query-triggered cases and 98.71% of observation-triggered cases. Benign leakage during these expanded tests remained near zero, registering at 0% and 0.14% respectively.
Impact on Model Capabilities and General Performance
While the sleeper agent behavior could be successfully embedded, the modifications did introduce measurable impacts on the models’ baseline capabilities. In separate, trigger-free benchmark tests conducted on the Qwen architecture, task success rates on Terminal-Bench fell from 46.59% for the clean, unmodified checkpoint down to 42.05% for both edited checkpoints. These benchmark shifts indicate that while the core utility of the assistant is largely preserved, structural tampering leaves a distinct performance footprint.
These findings present a complex challenge for enterprise deployments. Passing standard operational capability audits does not automatically answer the fundamental question of whether a model’s underlying weights have been tampered with. If a triggered response eventually translates into a high-privilege terminal command, the ultimate scope of potential damage depends entirely on the access permissions and tool capabilities granted to the host AI agent.
In response to these findings, Microsoft has recommended a multi-layered defense strategy for organizations deploying advanced AI agents. The company advises administrators to rigorously verify model provenance and monitor for unauthorized weight modifications. Furthermore, organizations should strictly restrict operating system privileges, limit outbound network access, and implement mandatory human-in-the-loop approval workflows for any consequential tool actions.
These recommended safeguards are designed to mitigate risks at both the foundational level—addressing the integrity of the model checkpoint itself—and the operational level, by containing what a compromised host agent can achieve in a live environment. At the same time, Microsoft cautions that successfully passing a standard security audit cannot guarantee entirely safe behavior from advanced AI systems, underscoring the ongoing cat-and-mouse dynamic between machine learning utility and safety engineering.