The artificial intelligence landscape has shifted at a breathtaking pace over the past month, introducing an entirely new category of AI model that has rapidly moved from a conceptual novelty to ubiquitous deployment. On September 15, TypeSafe AI released Jev, a system categorized as a "System One" model—a deliberate nod to Daniel Kahneman’s psychological framework of fast, intuitive thinking. Not long after, OpenAI announced its own Decisions API during its DevDay conference, opening a public beta by October 6. Concurrently, Cribl published cribl-decision, an open LoRA adapter designed for local execution, while other open-source offerings, such as Laya, have begun appearing across various open-source tooling ecosystems.
Unlike their text-generating predecessors, this new wave of models bypasses text generation entirely. Instead of generating paragraphs of conversational prose, operators hand these models a specific operational state alongside a set of typed questions. In return, the models deliver a definitive choice, a calculated score, or a binary yes-or-no response backed by a precise, calibrated probability. For security operations centers, industry observers suggest this breakthrough represents some of the most significant news of the year, though much of the ongoing industry discourse remains fixated on the wrong technological layer.
Why a SOC Should Be Excited
Security operations centers face a relentless influx of security alerts, making efficiency and automation paramount. Three distinct properties make these newly minted decision models a remarkably natural fit for alert triage and initial investigation workflows.
First, these models yield a quantitative metric that security teams can directly automate against. By receiving a typed answer alongside a calibrated probability, engineers can establish rigid, reliable operational thresholds. When asked whether a given alert is benign, the model returns a concrete probability. Security systems can then automatically close any alert with a probability exceeding 0.97. Conversely, alerts falling below a 0.6 threshold can be treated as likely incidents and escalated immediately, while anything residing in the ambiguous middle ground can be routed to a human analyst for a closer manual review. TypeSafe has even suggested implementing stricter thresholds for irreversible actions, creating a logical mapping between high-confidence automation and sensitive tasks like disabling a compromised user account versus simply appending an informational comment to a ticketing system.
Second, the operational economics of these models render them remarkably cost-effective, unlocking the financial viability of analyzing every single alert rather than cherry-picking a select few. Jev, for instance, is currently priced at roughly $42 per billion input tokens, delivering responses within a rapid window of 70 to 500 milliseconds. Consider a typical enterprise environment processing approximately 450,000 alerts annually, feeding a few thousand tokens into the model per alert. The resulting annual model expenditure lands around one hundred dollars. Consequently, the traditional economic argument for filtering alerts and exclusively investigating high-severity indicators of compromise has effectively evaporated.
Third, every single verdict generated by these models transforms into a permanent, auditable record. Because the output space is strictly defined in advance and the response carries its own statistical probability, security teams can log every decision, replay historical scenarios, and rigorously compare the model’s prediction against actual real-world outcomes. This audit trail is vastly superior and significantly easier to review than attempting to parse through verbose paragraphs of generated reasoning typical of older large language models. However, security professionals must keep one vital caveat in mind: when commercial vendors assert that these models cannot hallucinate, they simply mean the output strictly adheres to the predefined schema. A structurally flawless, well-formed answer can still be fundamentally incorrect.
But a Calibrated Guess Is Still Just a Guess
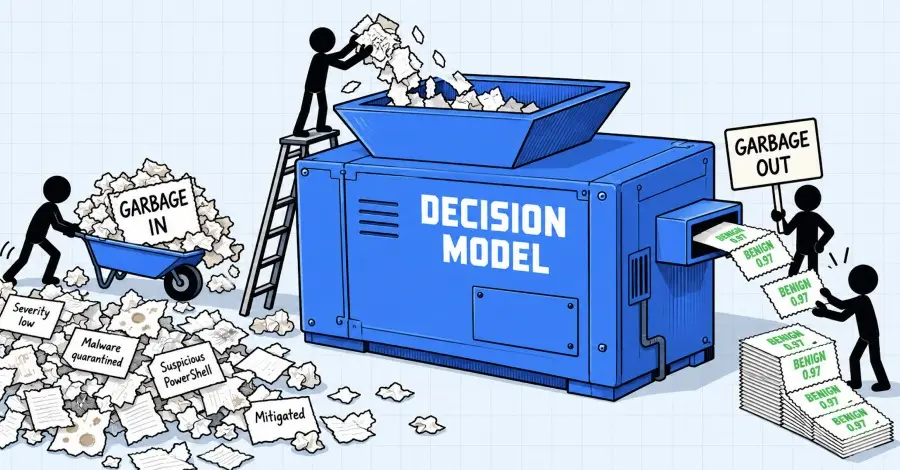
Despite the immense promise of automated decision-making, foundational engineering axioms remain undefeated. Garbage in still equates to garbage out.
Statistical calibration represents a promise regarding a data distribution. When a properly calibrated model asserts a 90 percent confidence level, it implies that across historical inputs exhibiting similar characteristics, the model is accurate roughly 90 percent of the time. Therefore, the critical question centers on what information constitutes that input. If the provided data consists merely of an alert title and a generic severity field, the model’s calibration applies exclusively to alerts sharing that specific title and severity level. The model remains entirely oblivious to the actual state of the underlying host machine.
This limitation carries profound operational implications in real-world environments. Data compiled across millions of customer alerts reveals a sobering reality regarding endpoint security. In a comprehensive dataset spanning 25 million alerts triaged over the course of a year, tens of thousands of alerts underwent live memory scans on targeted endpoints. A notable fraction of those scanned machines harbored active, ongoing infections, yet a majority of those infected systems had already been incorrectly reported as fully mitigated by standard Endpoint Detection and Response solutions.
Consider the perspective of a decision model encountering such an alert: malware is detected, the threat is supposedly quarantined, and the event carries a low severity rating. A perfectly calibrated model should logically close the alert with high confidence, because the vast majority of alerts exhibiting those exact parameters are genuinely benign. In this scenario, the model successfully performed its designated function; the underlying input data provided to it was simply flawed.
Severity classifications suffer from a parallel vulnerability at scale. Approximately one percent of genuine, verified security incidents trace back to alerts categorized at the absolute lowest severity levels. In an enterprise processing 450,000 alerts annually, that percentage translates to dozens of real threats slipping past conventional severity filters—amounting to roughly one critical security incident missed every week. Cribl’s own official model card transparently acknowledges these boundaries, noting that decision models are susceptible to overconfidence and sensitive to the specific wording of prompts and candidate choices. This honesty applies universally across the entire class of decision models.
What Evidence Actually Looks Like
To understand effective security investigations, consider a forensic crime scene. Describing a crime scene to a conversational chatbot in broad, general terms yields only a plausible theory. Conversely, introducing a dedicated DNA lab, physical fingerprints, forensic evidence, and verified witness statements completely changes the investigation. No one needs to debate which methodology reliably identifies the correct suspect.
Security investigations operate under identical principles. Industry experts increasingly describe this methodology as Security Context Engineering—the deliberate process of transforming a raw, ambiguous alert into a comprehensive set of verified facts before any human analyst or automated model issues a final verdict.
When evaluating a suspicious process, the typical alert might merely flag "Suspicious PowerShell," whereas comprehensive forensic evidence reveals the complete process tree, the parent application, the exact command-line arguments, and the physical script residing on the disk. Similarly, while a standard alert provides a file hash and a basic reputation score, forensic analysis uncovers the precise behavioral actions performed when the file was detonated, the network communication endpoints it contacted, and any secondary files it dropped onto the system.
Regarding endpoint status, relying solely on an EDR "mitigated" tag can be dangerously misleading. Live memory scans frequently reveal injected code, rootkits, or fileless payloads actively operating in volatile memory—specifically where file-based quarantine statuses lack visibility. Furthermore, identity alerts benefit immensely from contextual depth. Standard logs might display a routine username, whereas true forensic context identifies where the user logged in, from which specific hardware device, and whether that access pattern aligns with historical user behavior.
The most prevalent threat families frequently discovered lurking in live memory include advanced adversarial tools designed specifically to operate without touching the disk—precisely where traditional quarantine mechanisms fail to look. Collecting this vital evidence is not an exotic engineering challenge; it mirrors the exact workflow a skilled incident responder executes manually. The true operational hurdle lies in automating the collection of this evidence for every single alert in under a minute.
The Hardest Context Is What Normal Looks Like
While forensic evidence provides an objective account of what transpired on a specific machine, it does not inherently indicate whether that behavior is expected within a given corporate enterprise. Identity alerts illustrate this information gap clearly. Historical security data indicates that a substantial majority of identity alerts are ultimately classified as benign. For instance, impossible travel alerts are verified as genuine compromises only a small fraction of the time, with routine corporate virtual private network usage driving a significant portion of those anomalies.
An isolated decision model cannot inherently know that a specific employee in the finance department routinely logs into corporate networks from abroad, or that an automated security alert fires on enterprise build servers every single time the DevOps engineering team pushes a software release. Historically, that institutional knowledge resided exclusively inside the memory of the most senior security analysts—information that walks out the door when personnel leave the organization.
This organizational context is uniquely challenging to manage because it cannot simply be purchased off-the-shelf; it is hyper-specific to each individual corporate environment. Moreover, this context constantly decays as organizational assets, users, and software tooling evolve on a weekly basis. A static snapshot loaded during initial employee onboarding becomes obsolete within a single quarter.
Consequently, organizational context must function as a continuous feedback loop. Security systems must learn from historical casework and the specific ways analysts previously resolved similar alerts. They must pull live operational context mid-investigation when endpoint memory alone proves insufficient. Finally, every automated verdict must be systematically compared against its actual outcome, writing the resulting lesson back into the organizational repository. This final validation step ensures that a 90 percent confidence threshold genuinely reflects accuracy within the specific enterprise environment rather than simply performing well on a generalized vendor benchmark.
A Forensic Approach to Alert Triage and Investigation
Organizations that approach alert triage through a rigorous forensic lens establish clear operational principles: collect the underlying evidence first, and render decisions second. By leveraging advanced code-level analysis, platforms can compare every binary executing in memory against extensive databases of trusted and malicious code, successfully catching both known malware variants and novel threats that reuse components of recognized attack tools.
Automated live memory forensics play a vital role when initial alerts lack sufficient evidence or display indicators of fileless attacks and code injection. Executing lightweight endpoint scanners on targeted machines allows security systems to gather comprehensive process trees, loaded executables, targeted memory dumps, and the underlying files associated with scheduled tasks and system autoruns. Combined with sandbox detonation, network traffic analysis, and institutional memory systems that catalog organizational assets, user behavior, and enterprise asset baselines, security operations can achieve unprecedented efficiency.
Ultimately, decision models provide a fast, economical, and auditable mechanism for executing the final step of the triage pipeline. However, whether that final decision is correct will always depend entirely on the quality and depth of the evidence and context gathered before the model is ever invoked. As frontier models and decision systems continue to evolve rapidly, the ultimate competitive advantage for security teams will not lie in the underlying commercial model, but in the proprietary context and forensic rigor they feed into it.